What our production models actually do
Worked pipelines, each built only on our production models: maintained, benchmarked, and the ones we'd point anyone to today. Real code and published numbers.
from olaverse import LIDNeural608
from olaverse.nlp import Diacritizer

lid = LIDNeural608()
lid.predict("Habari za asubuhi")         # → 'swh_Latn'

d = Diacritizer(model="diacnet-2.0", lang="yor")
d.restore("O so fun ara re pe oun ko ni isoro kankan.")
# → 'Ó sọ fún ara rẹ̀ pé òun kò ní ìṣòro kankan.'
Every pipeline below runs on the same SDK — read the docs
Start from the job, not the model
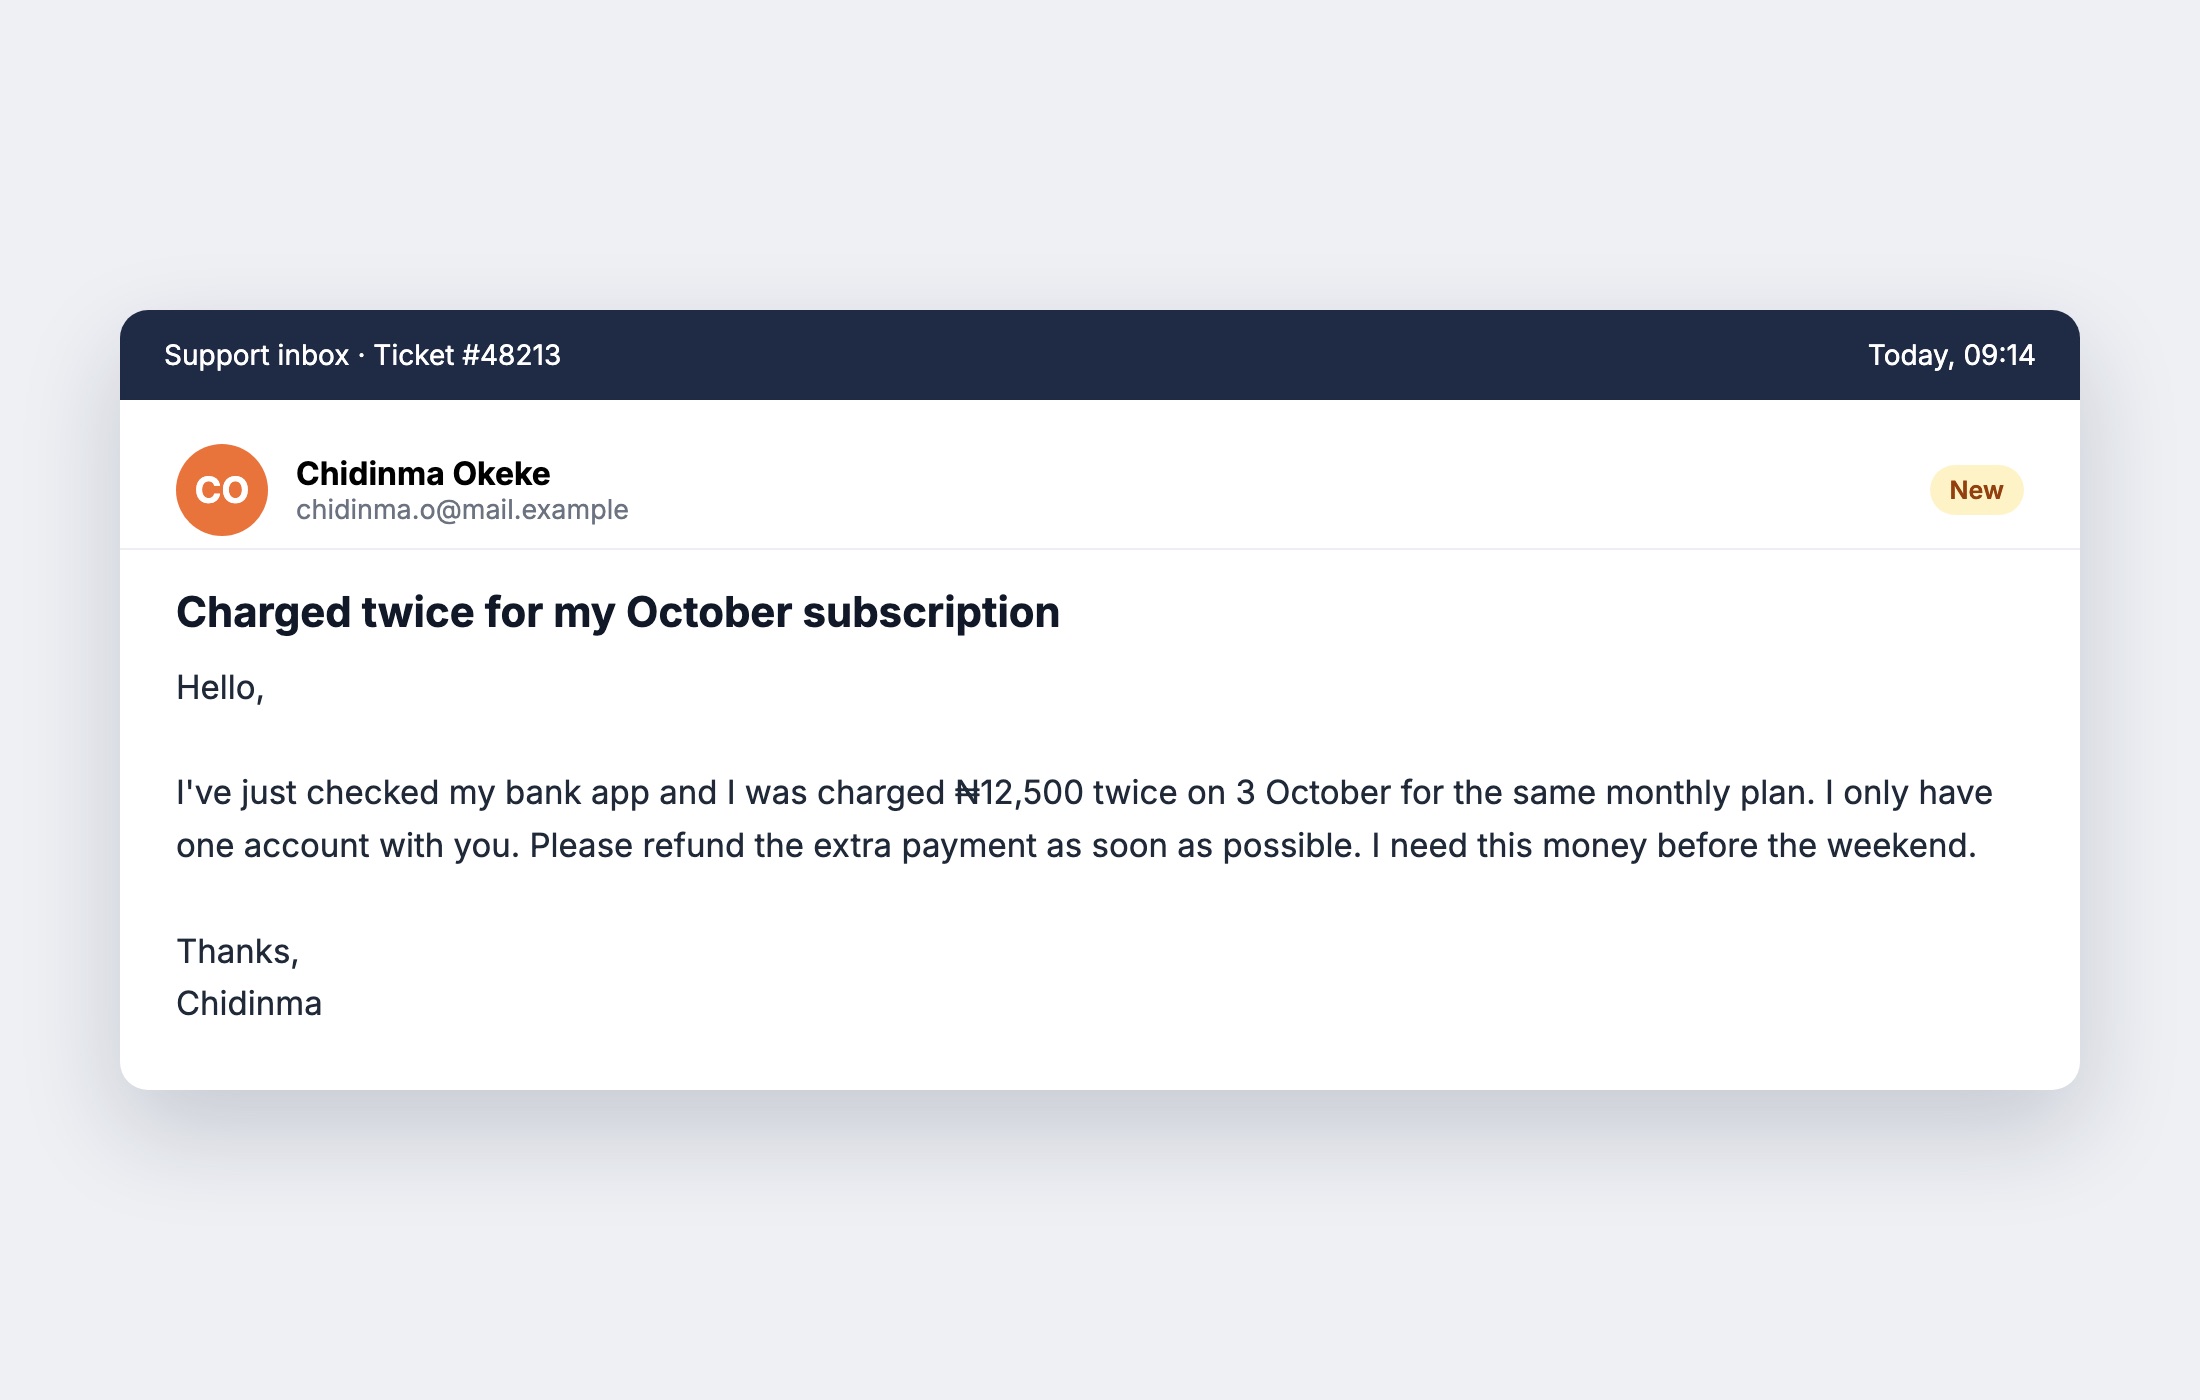
Automated decisions
Route, flag and score tickets, chats and records with calibrated probabilities, in English and eight African languages, from one self-hosted model instead of a chain of LLM calls.
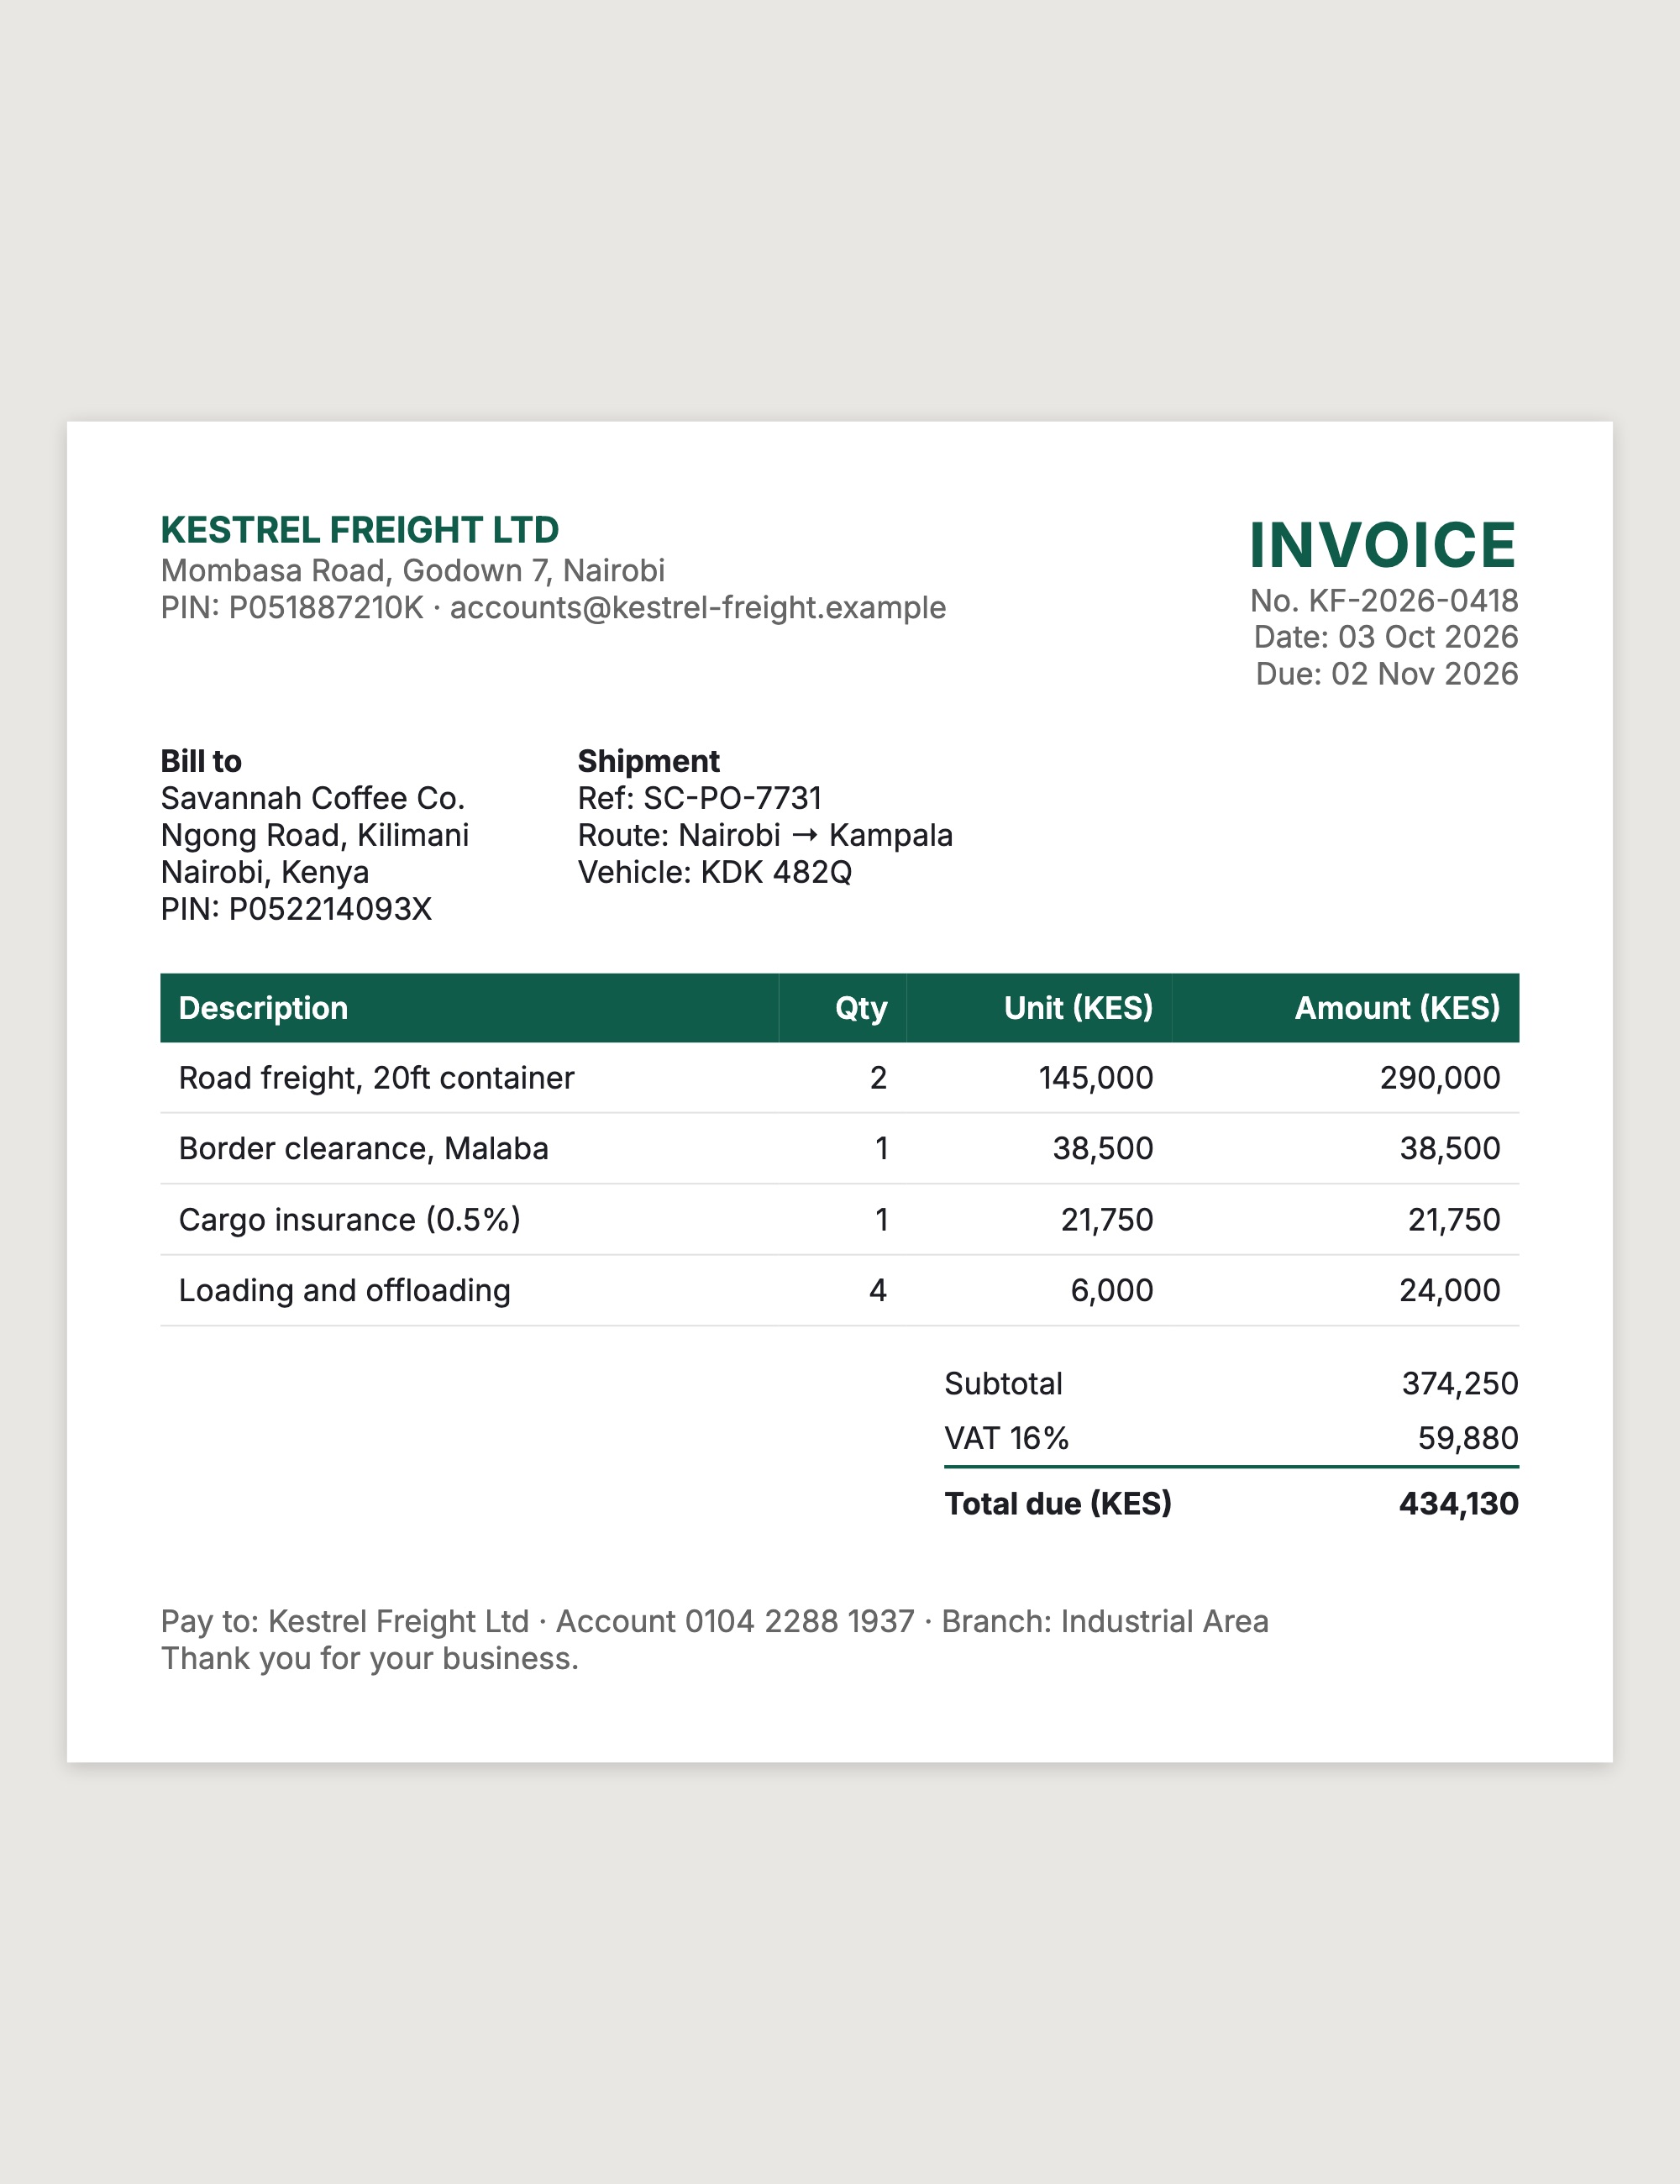
Document extraction
Fill a JSON template from a photo, a scan or plain text, with a calibrated confidence on every field. Built for African documents and currencies, in English and African languages.
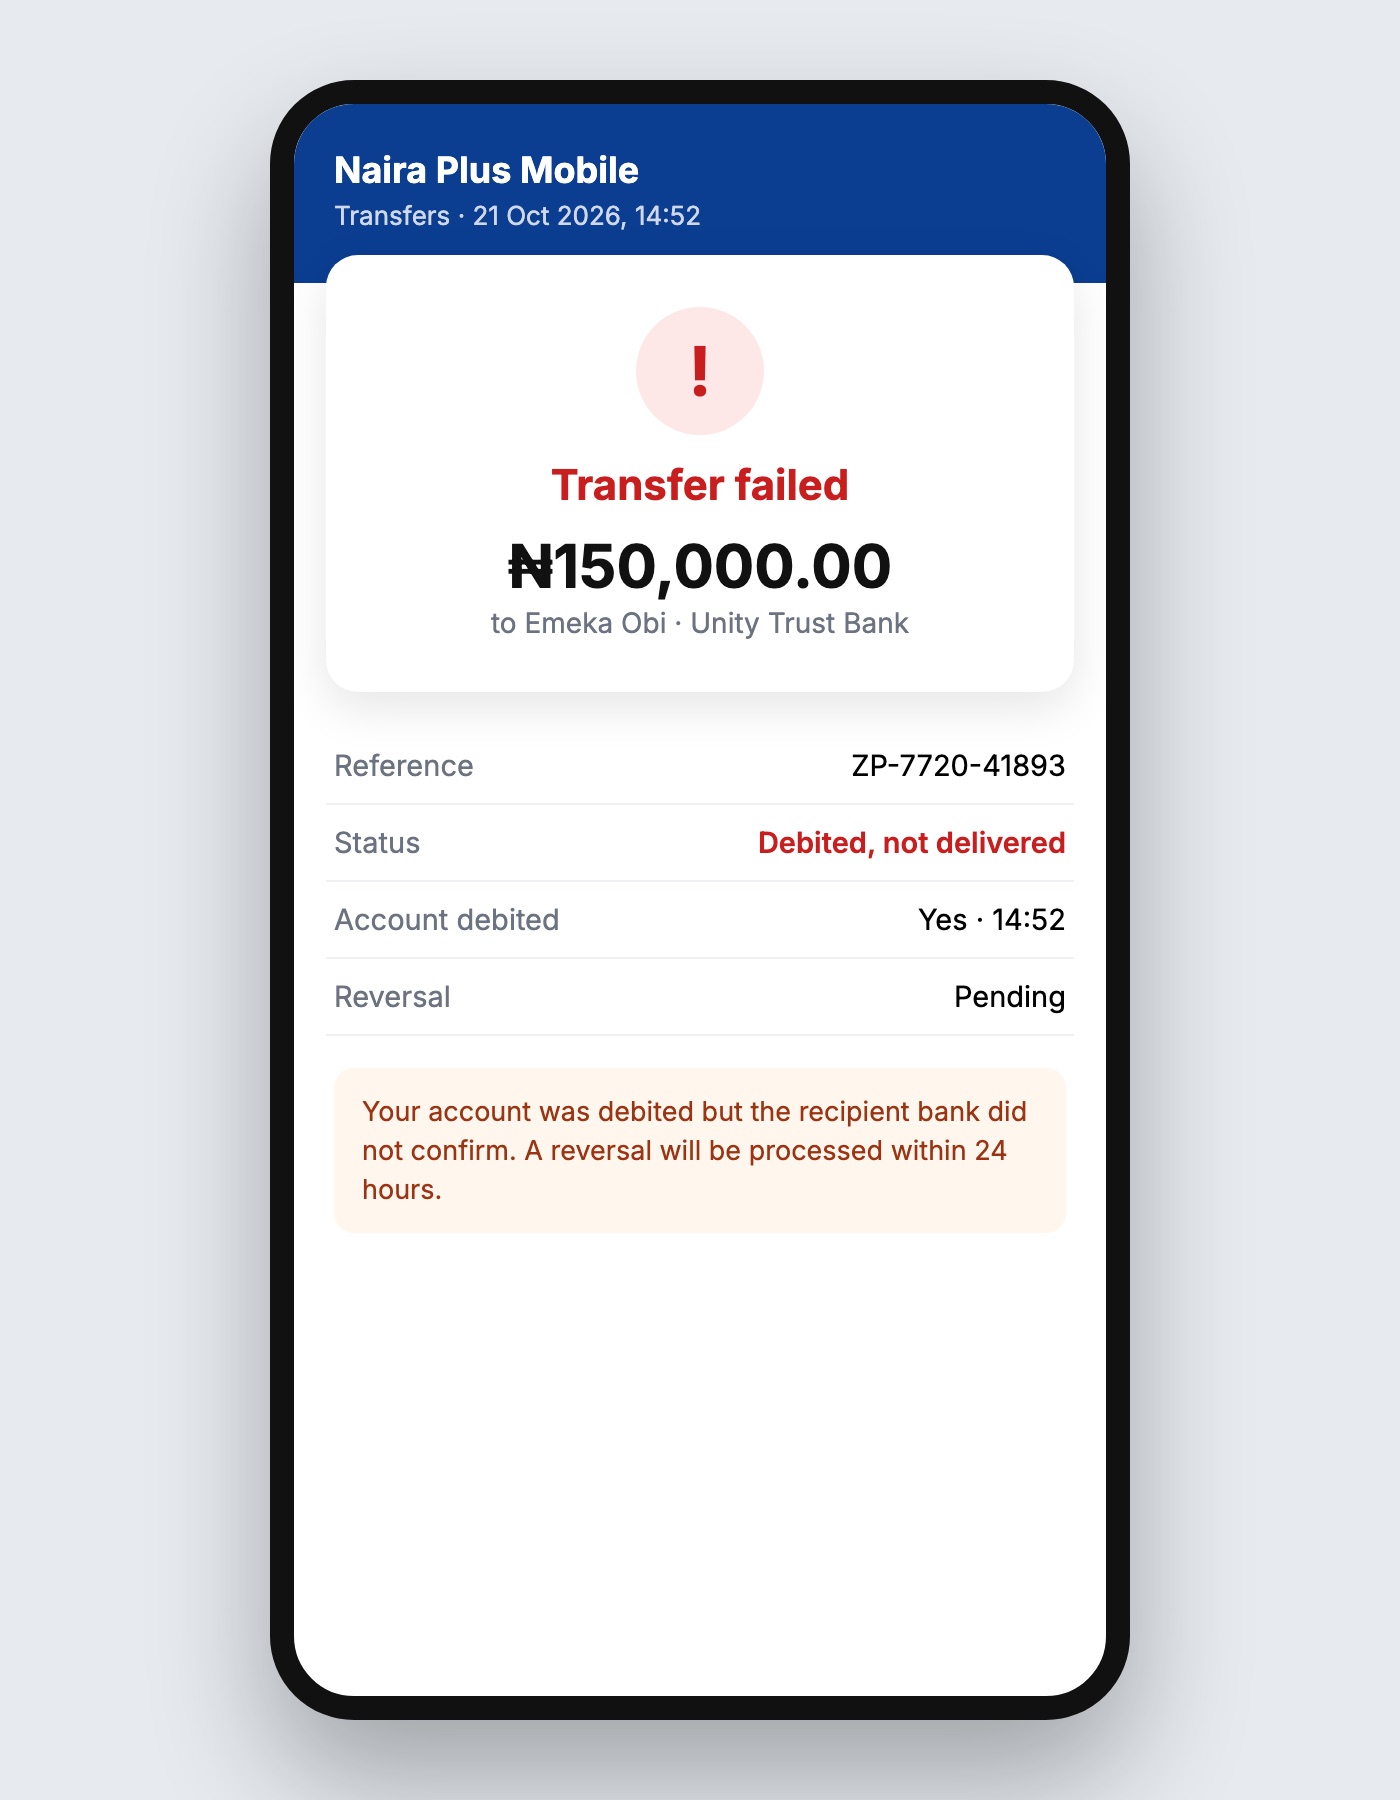
Payment messages
Pull the amount, sender, reference and date out of mobile-money and bank SMS, then decide in one pass whether it is genuine, which account it belongs to and whether anyone needs to look at it.
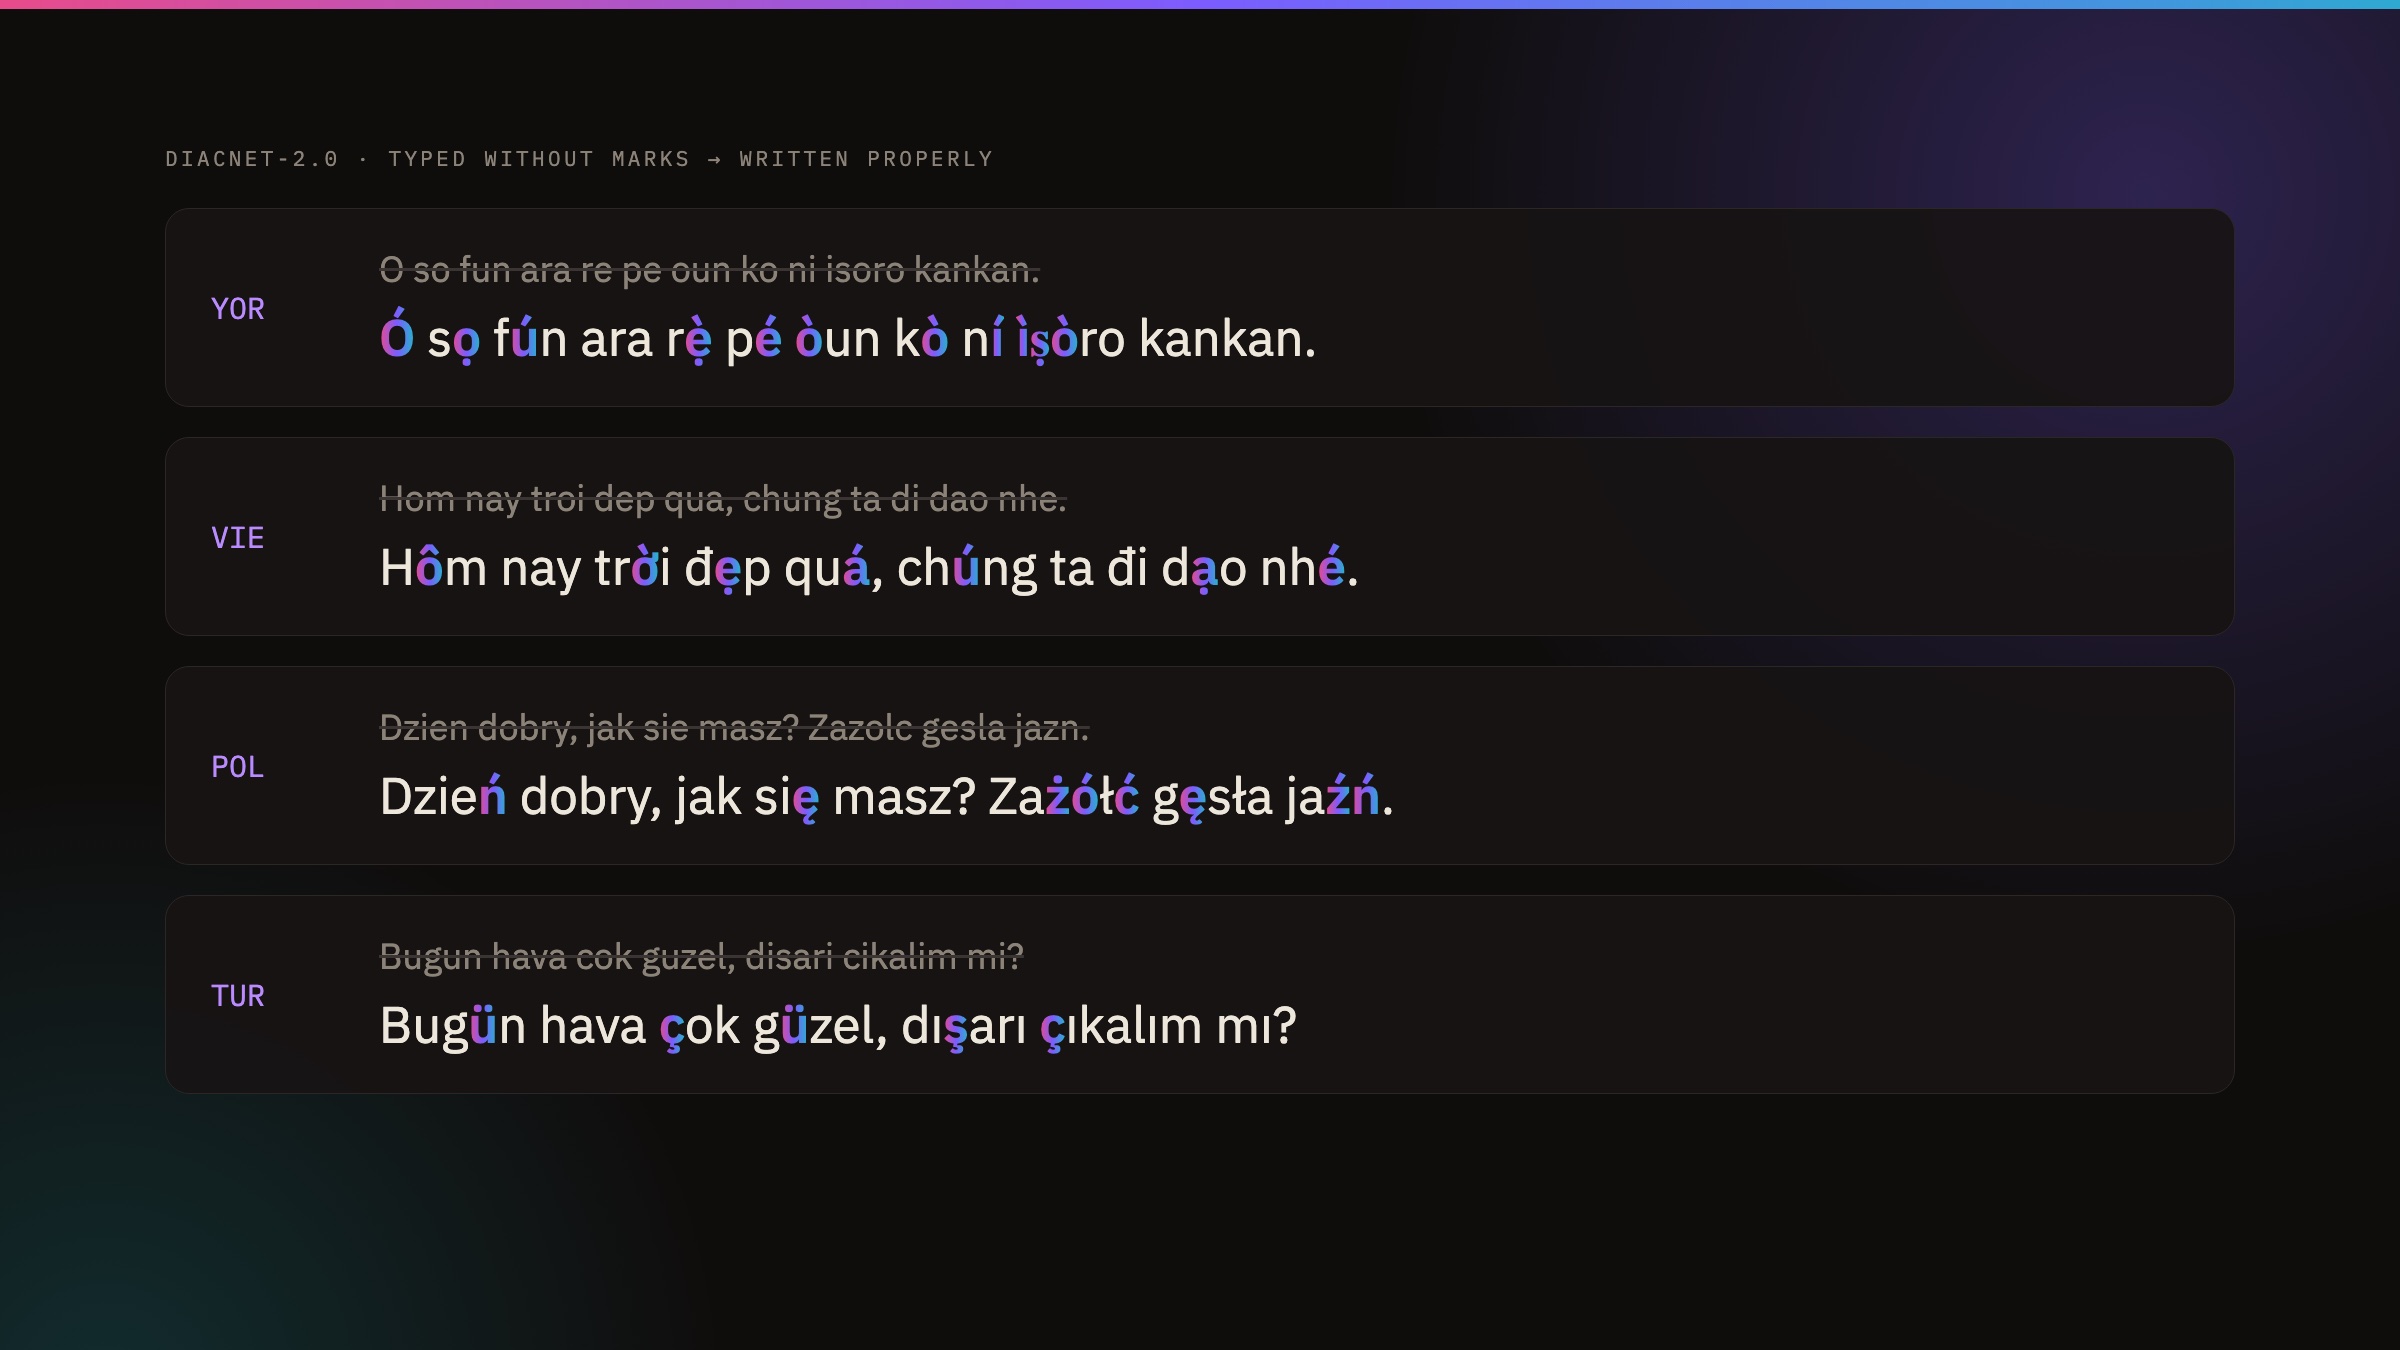
Diacritic restoration
Restore diacritics and tone marks on text that was typed, scraped, or keyed in without them, across 11 languages from Yorùbá and Igbo to Vietnamese, Polish and Arabic.
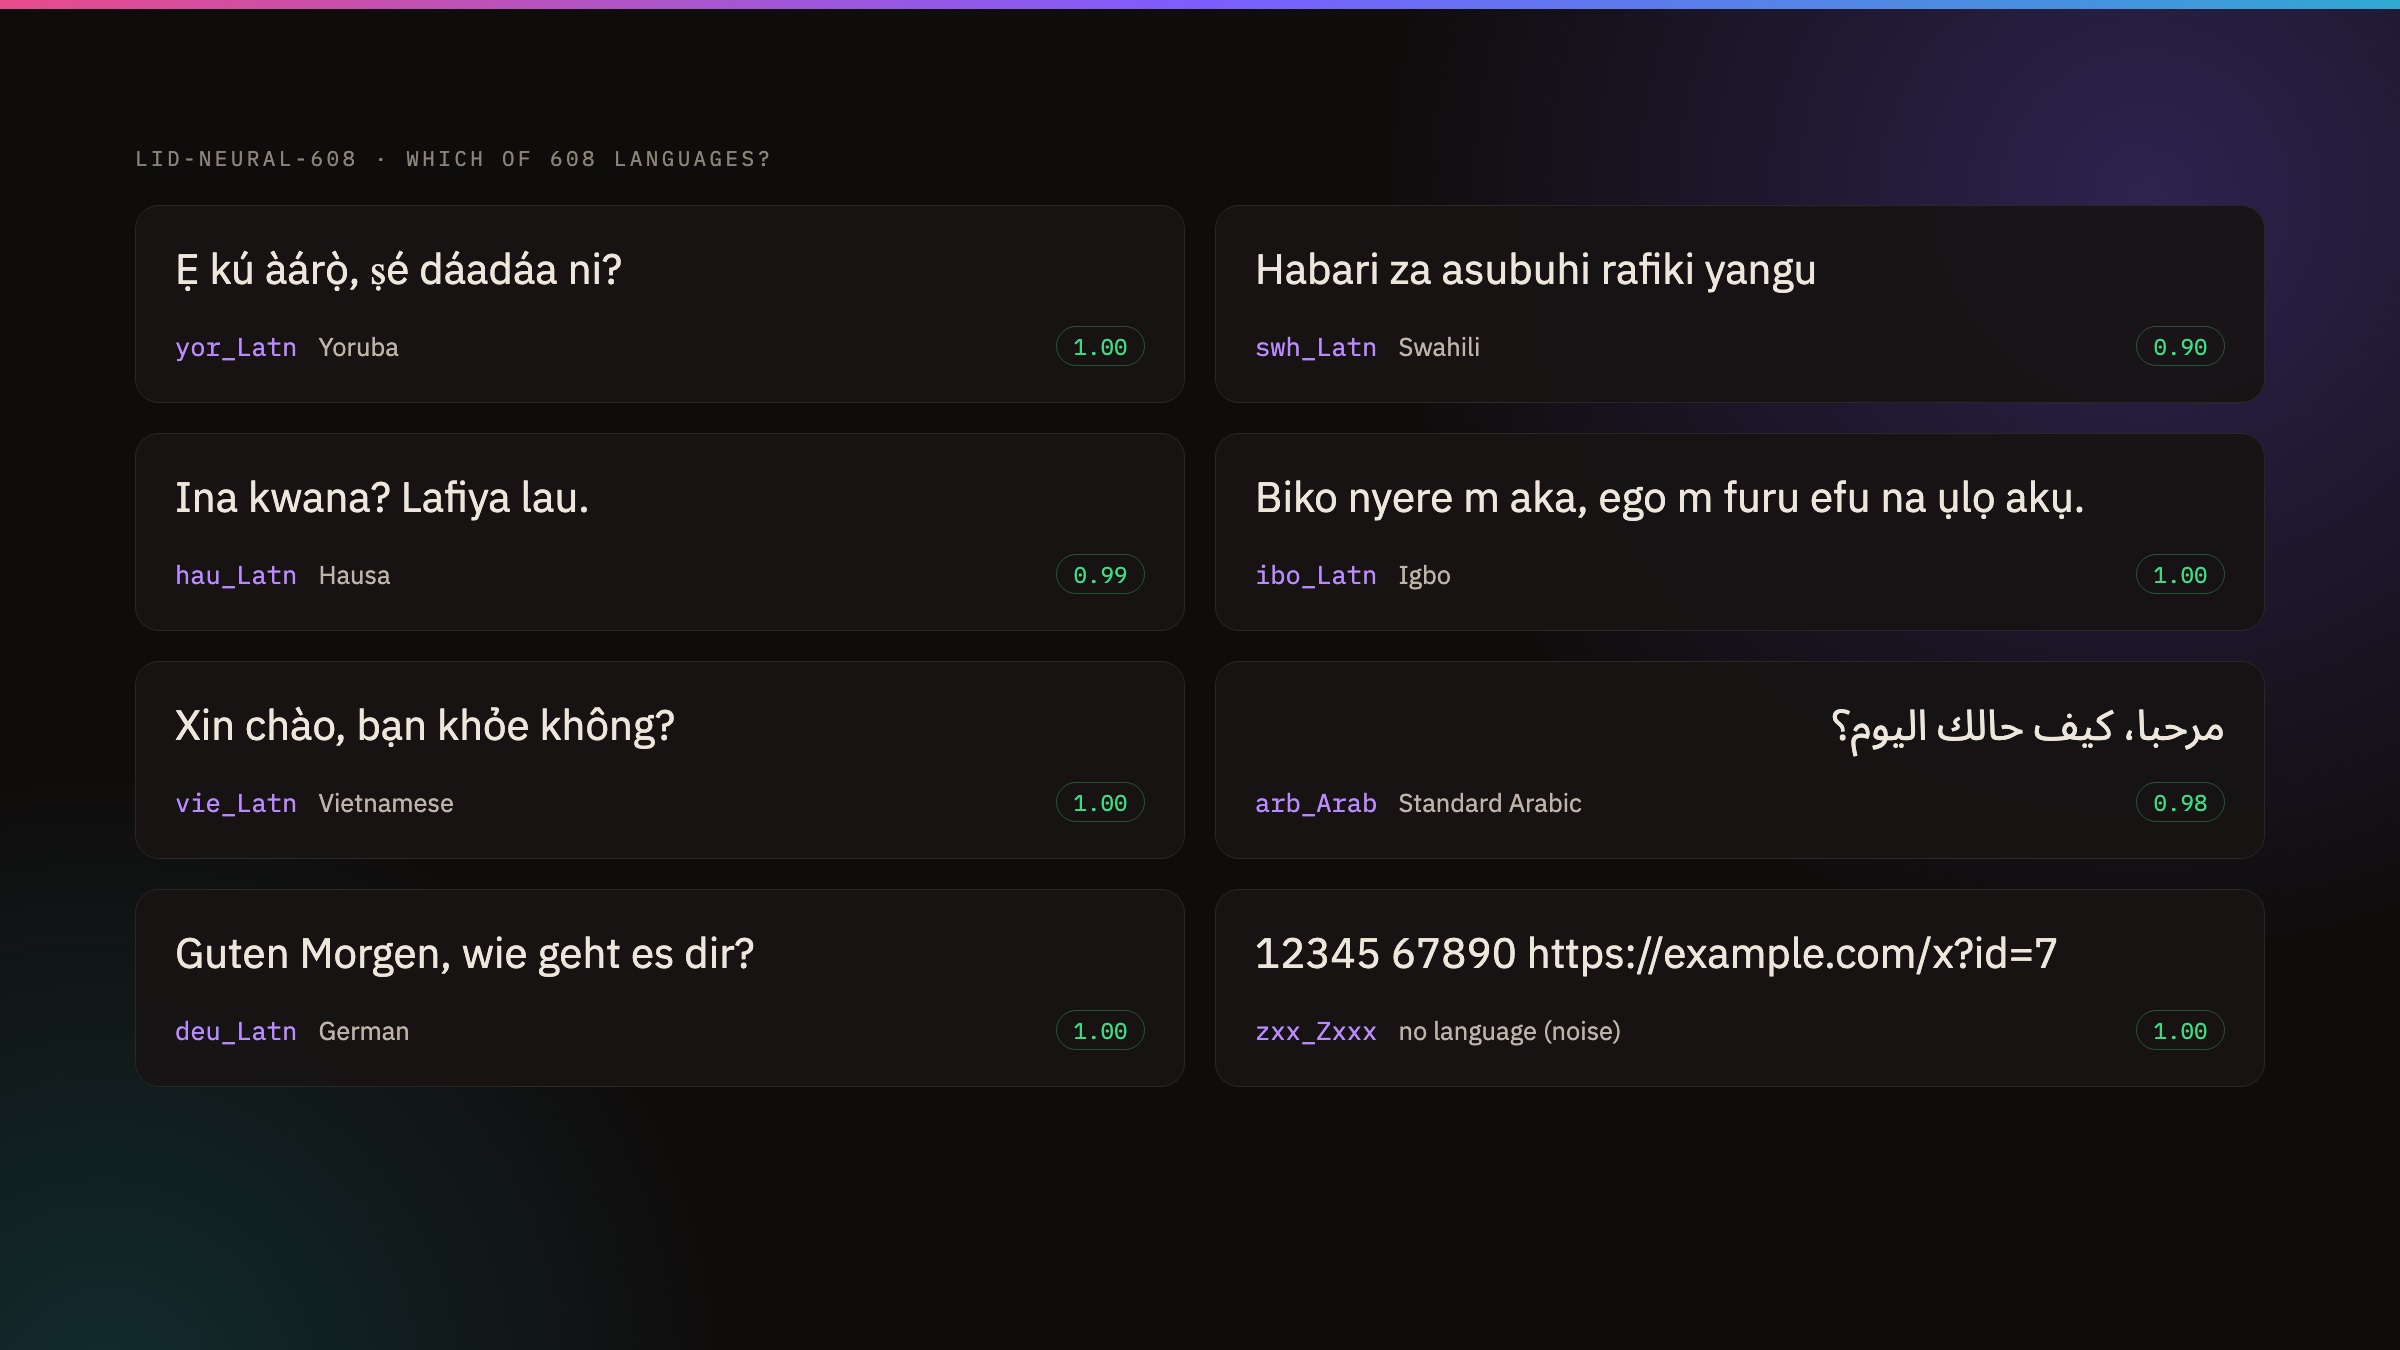
Language routing
Detect the language of support tickets, chat messages, queries, and documents across 608 languages, built African-first and accurate on the short text real products see.
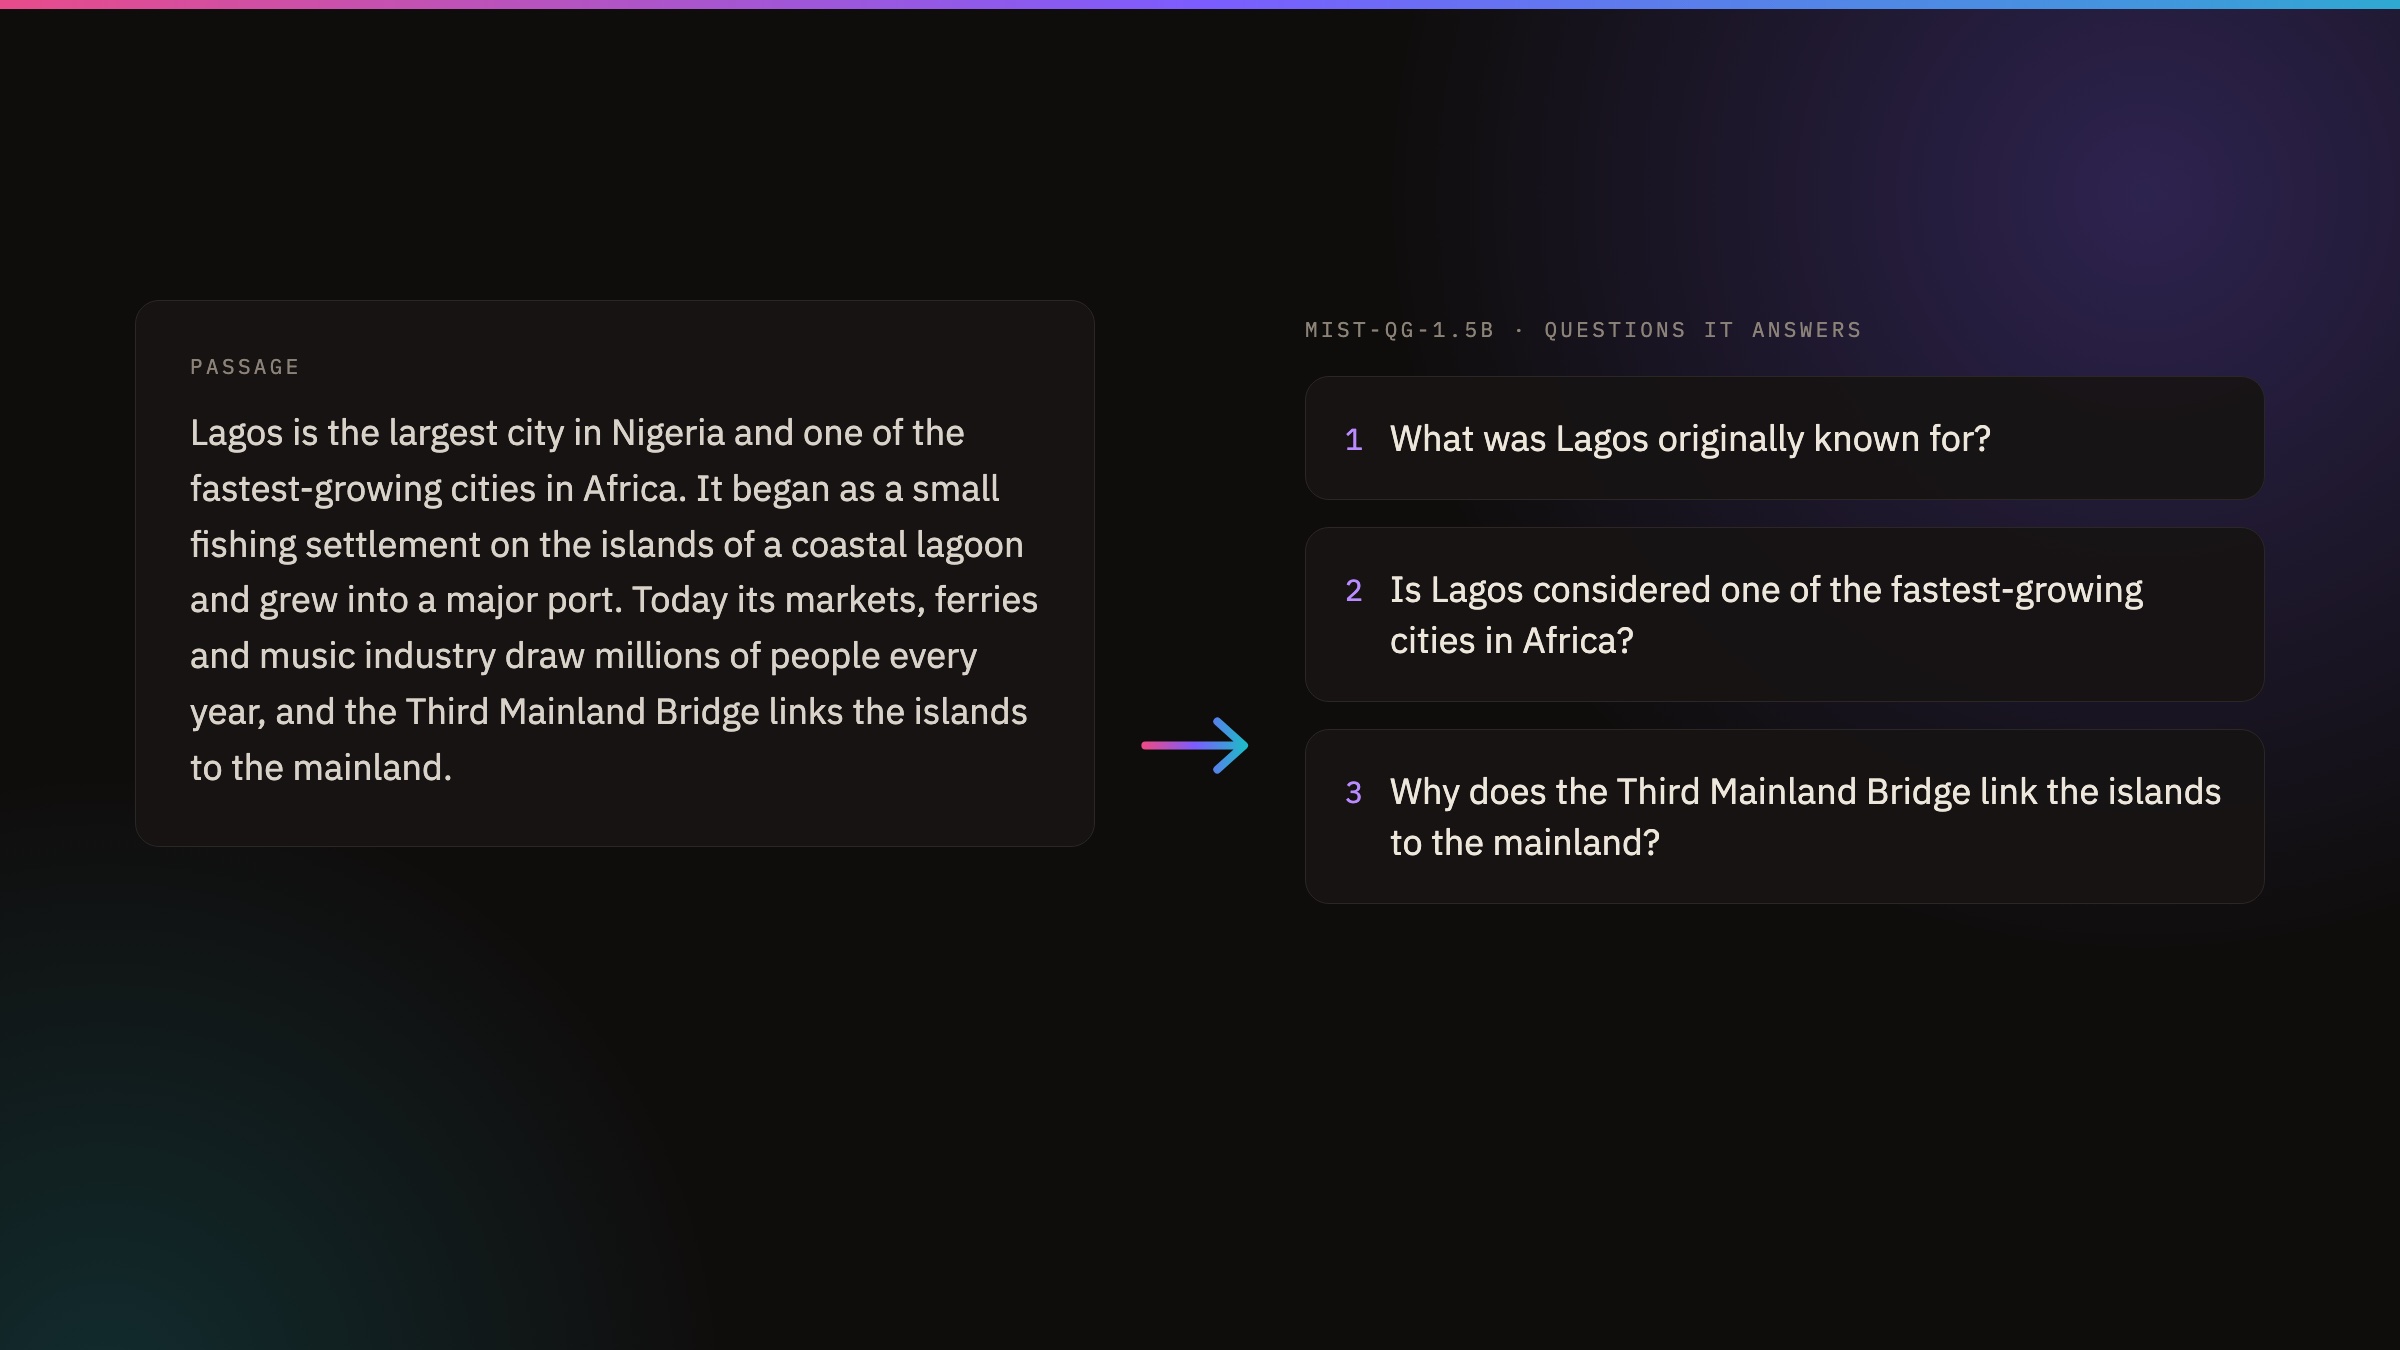
Question generation
Generate the questions a passage answers, in 324 languages, in its own language or across languages, for quizzes, reading comprehension, help-centre FAQs and assessment banks.
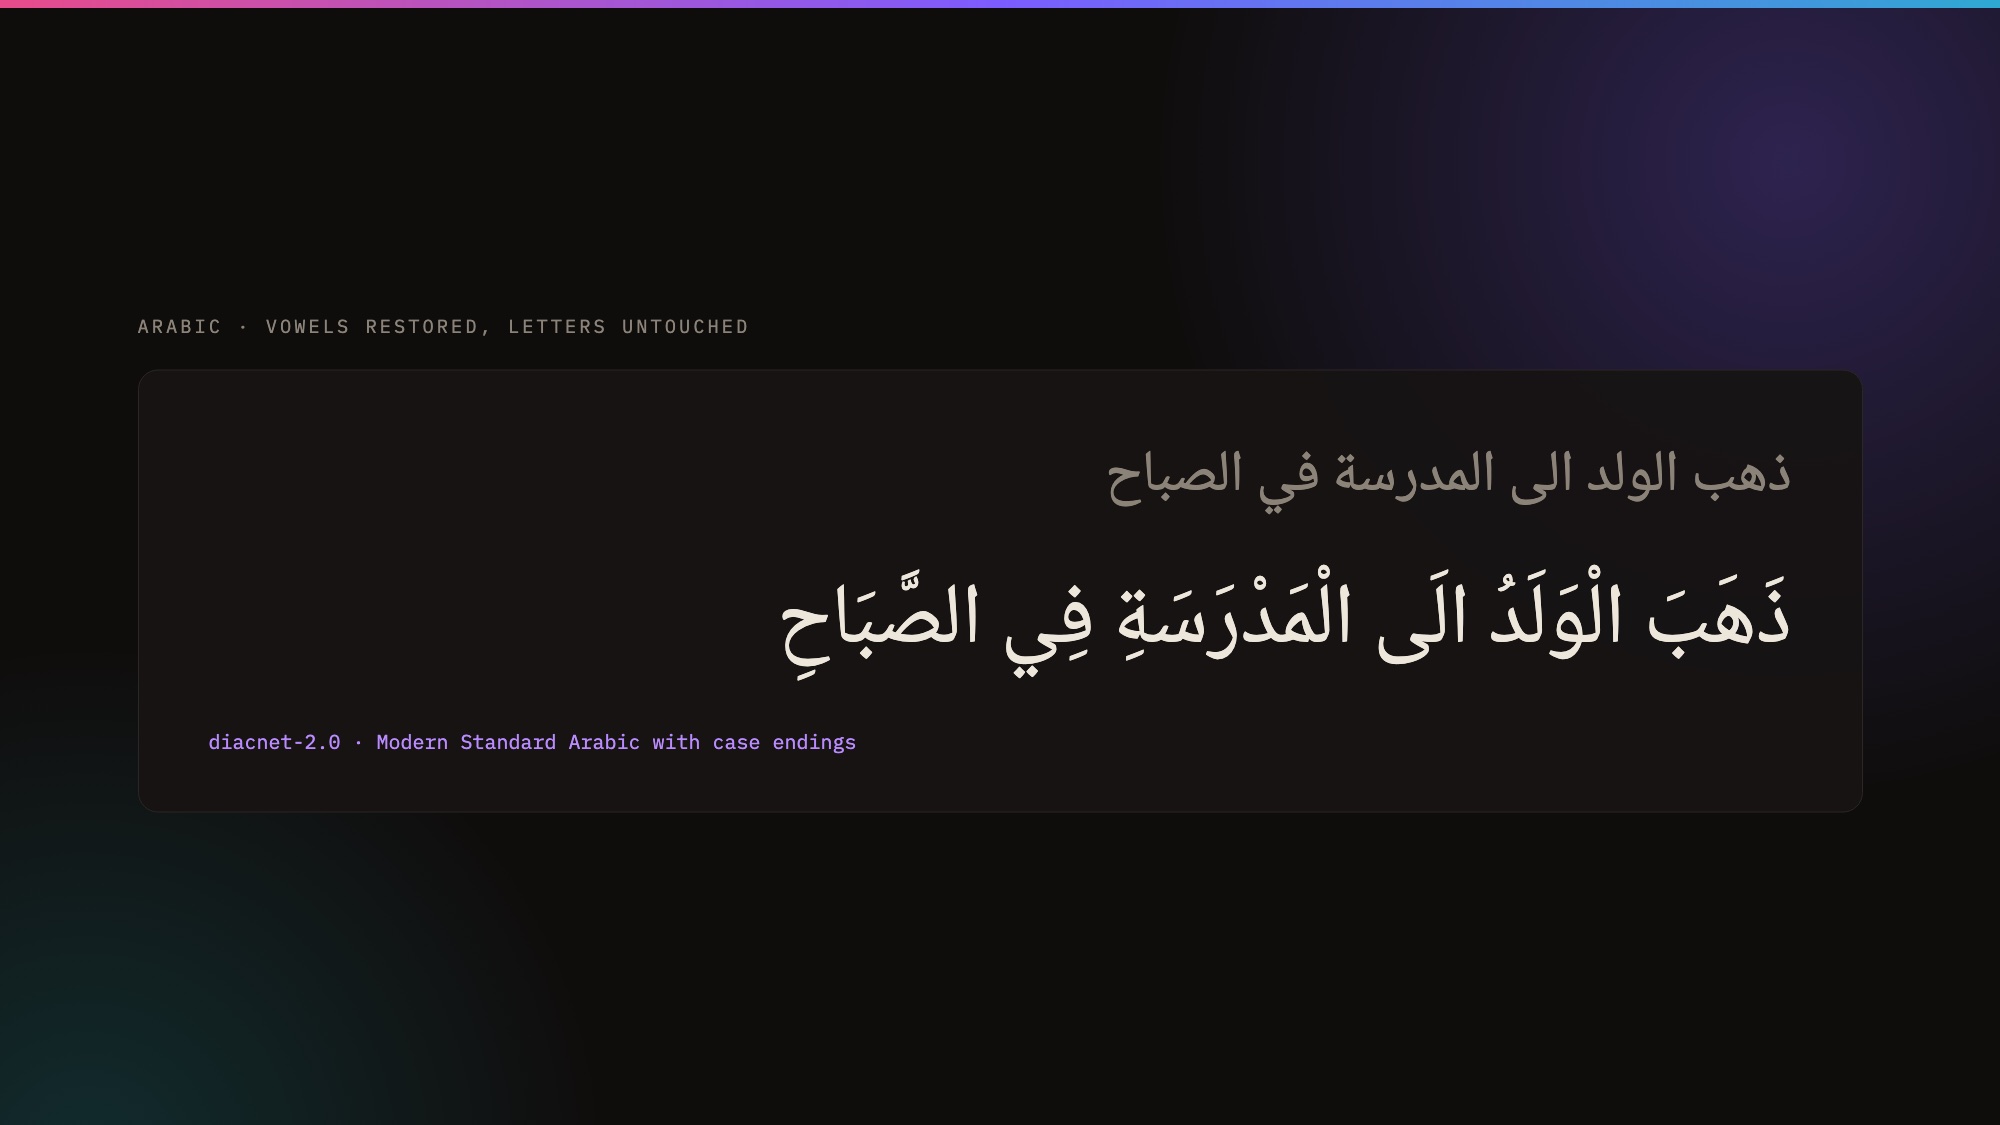
Arabic diacritization
Restore Arabic tashkīl, with or without case endings, for text-to-speech, teaching material and readable copy, from models that also cover ten other languages.
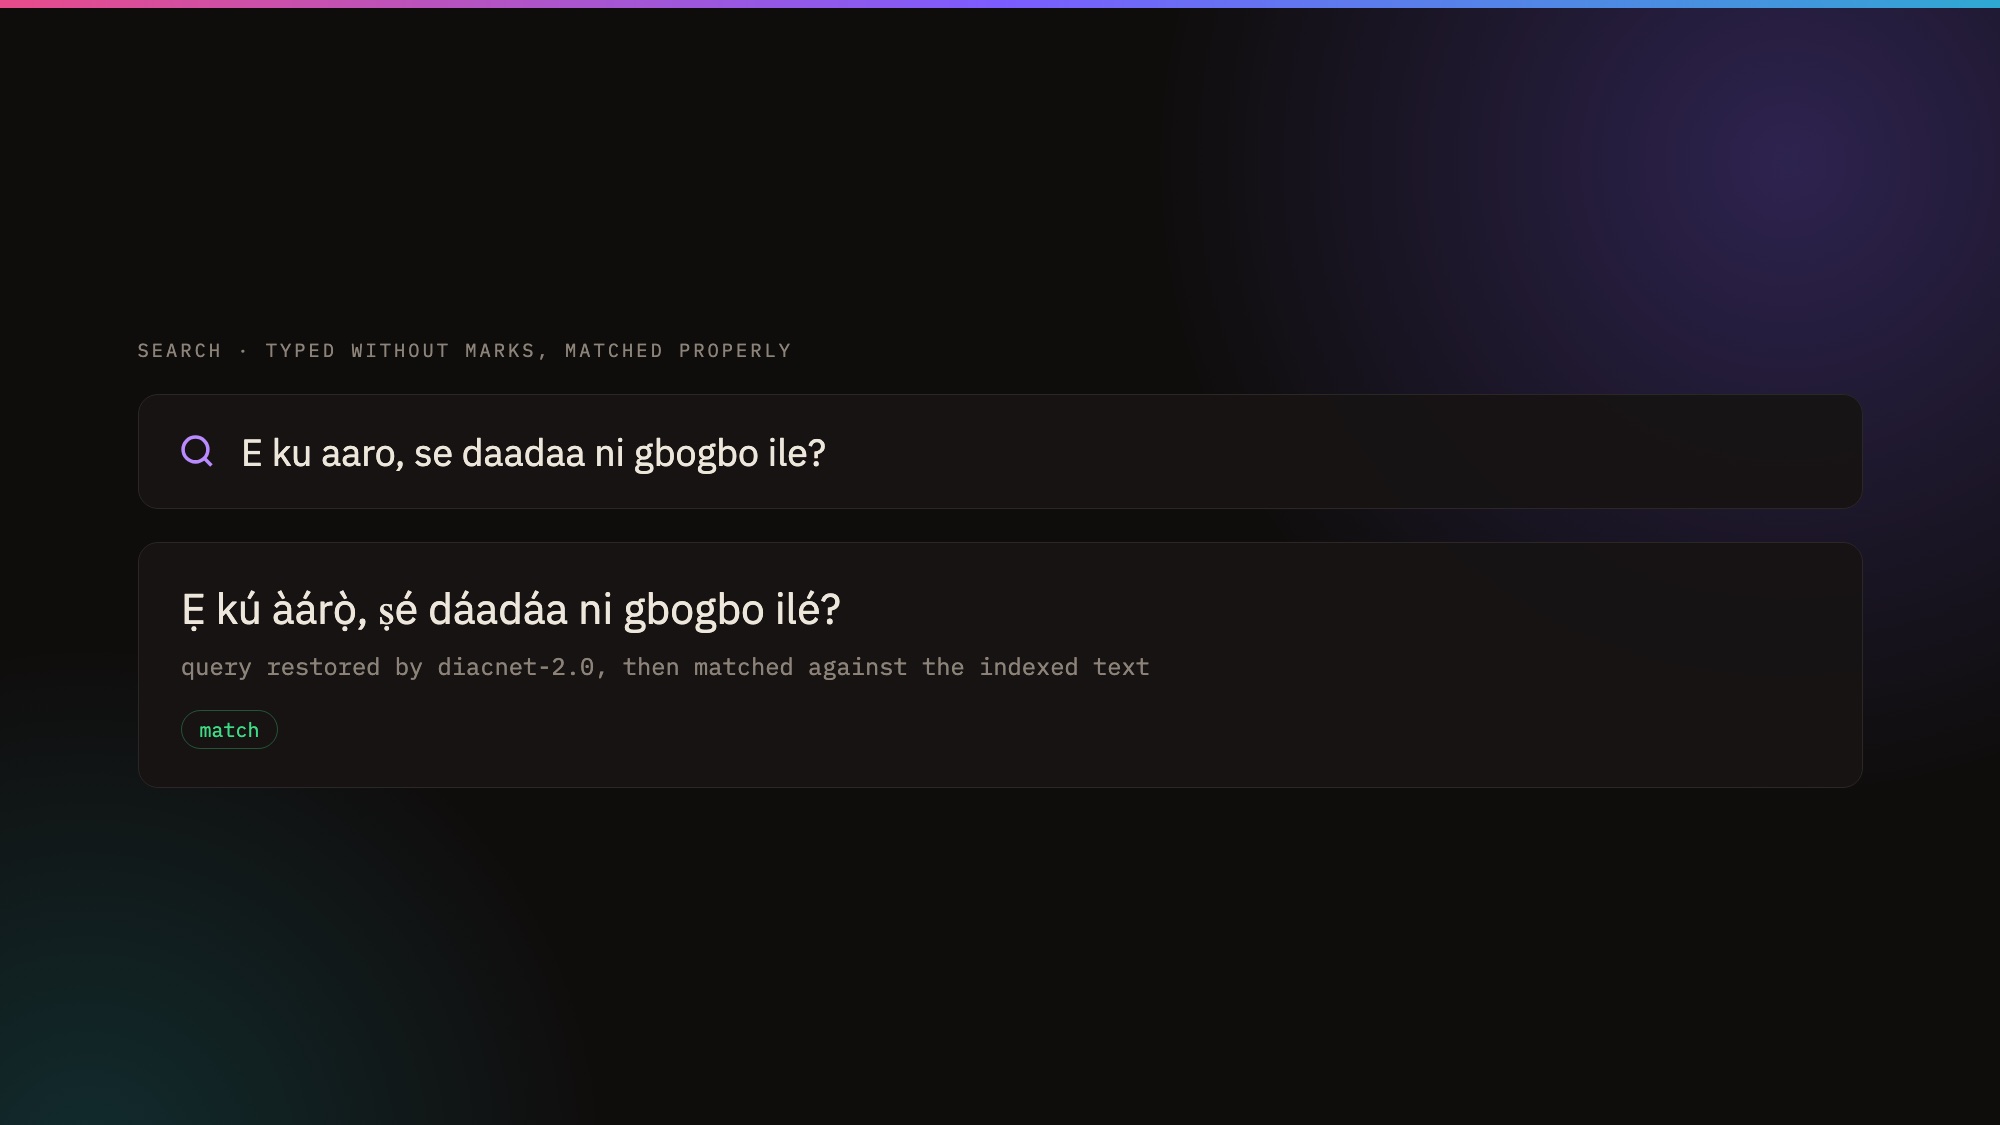
Search that matches
Restore the marks your documents lost, then match on an accent-folded key, so a user typing "oko" finds "ọkọ" and still sees it written properly.
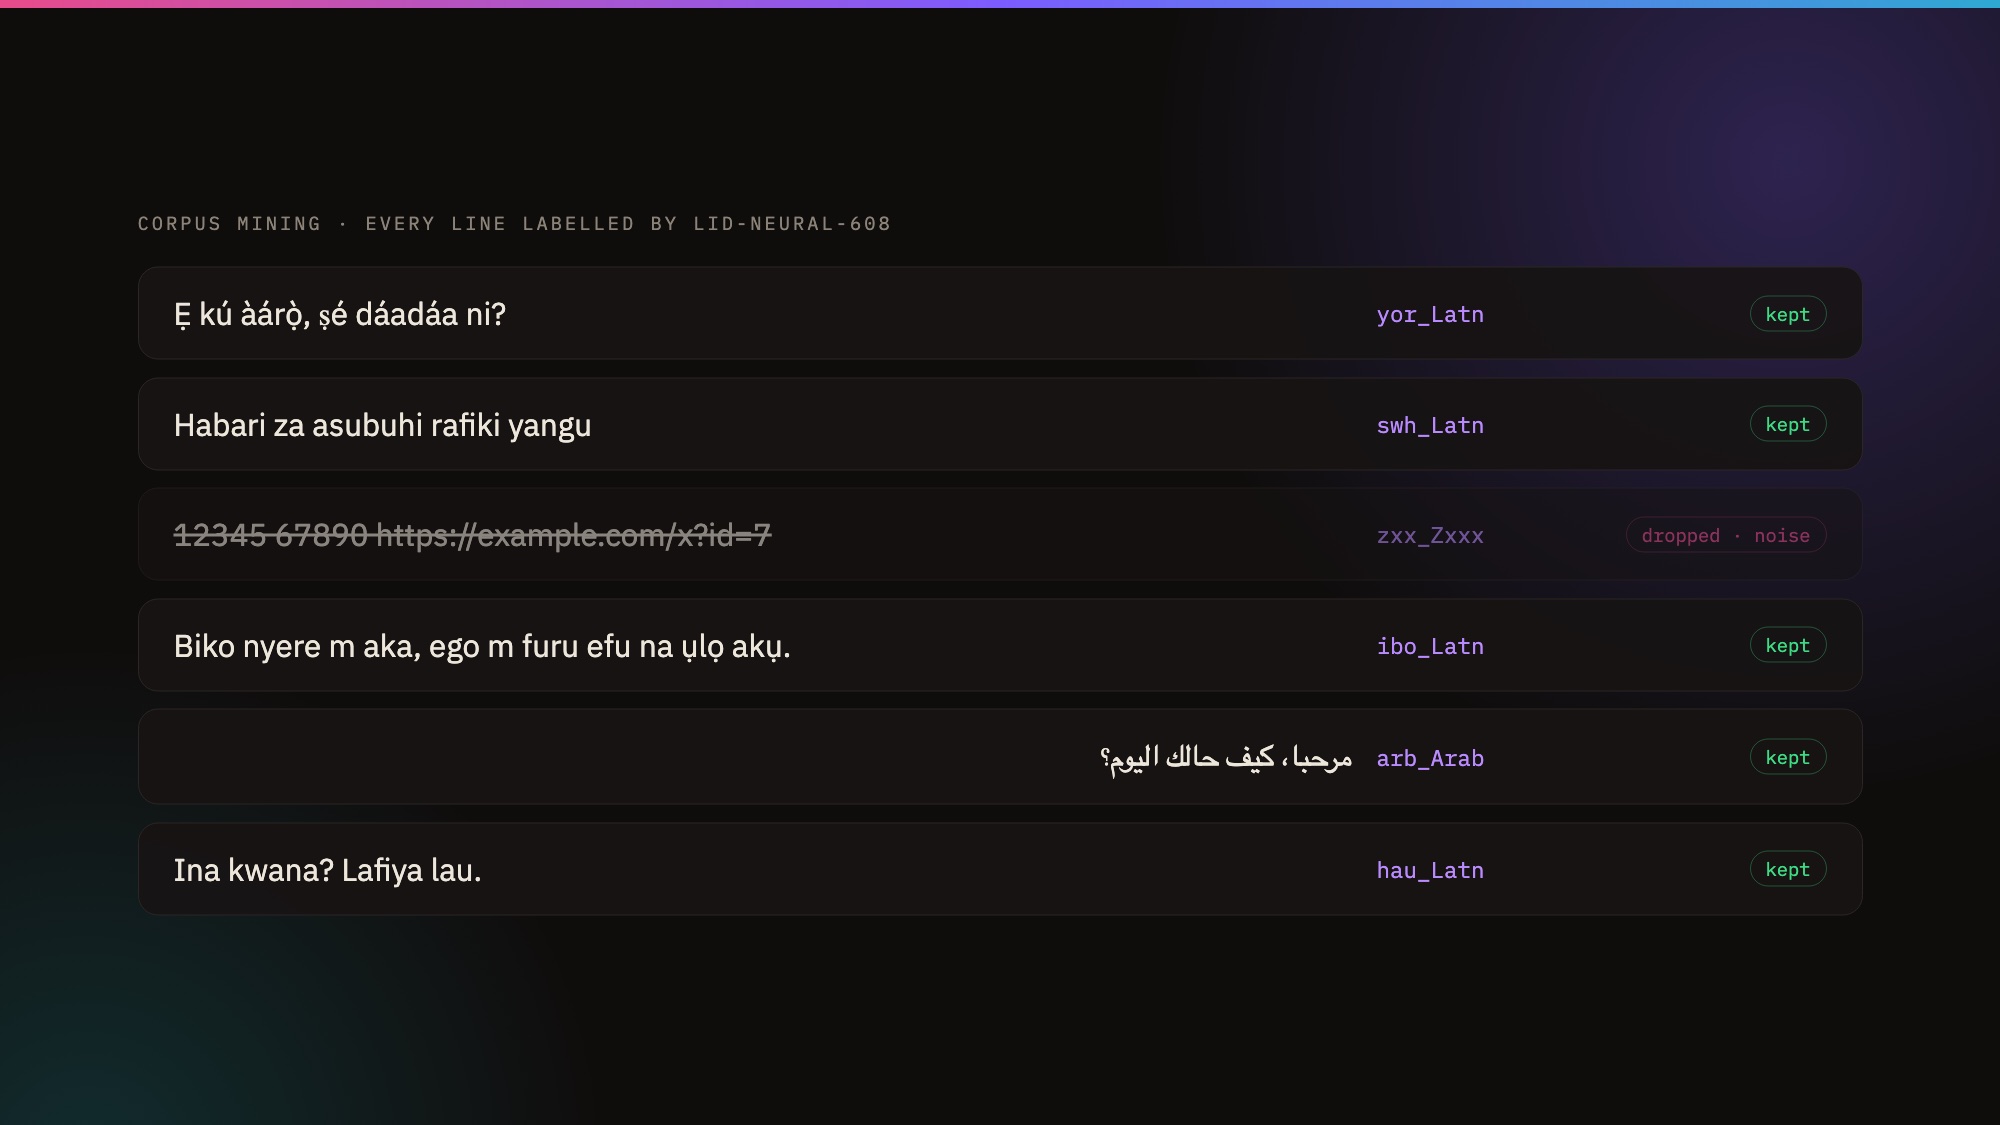
Low-resource corpus mining
Sort billions of web documents into 608 languages on CPUs, drop the junk, and pull out the African and low-resource text that general detectors misfile.
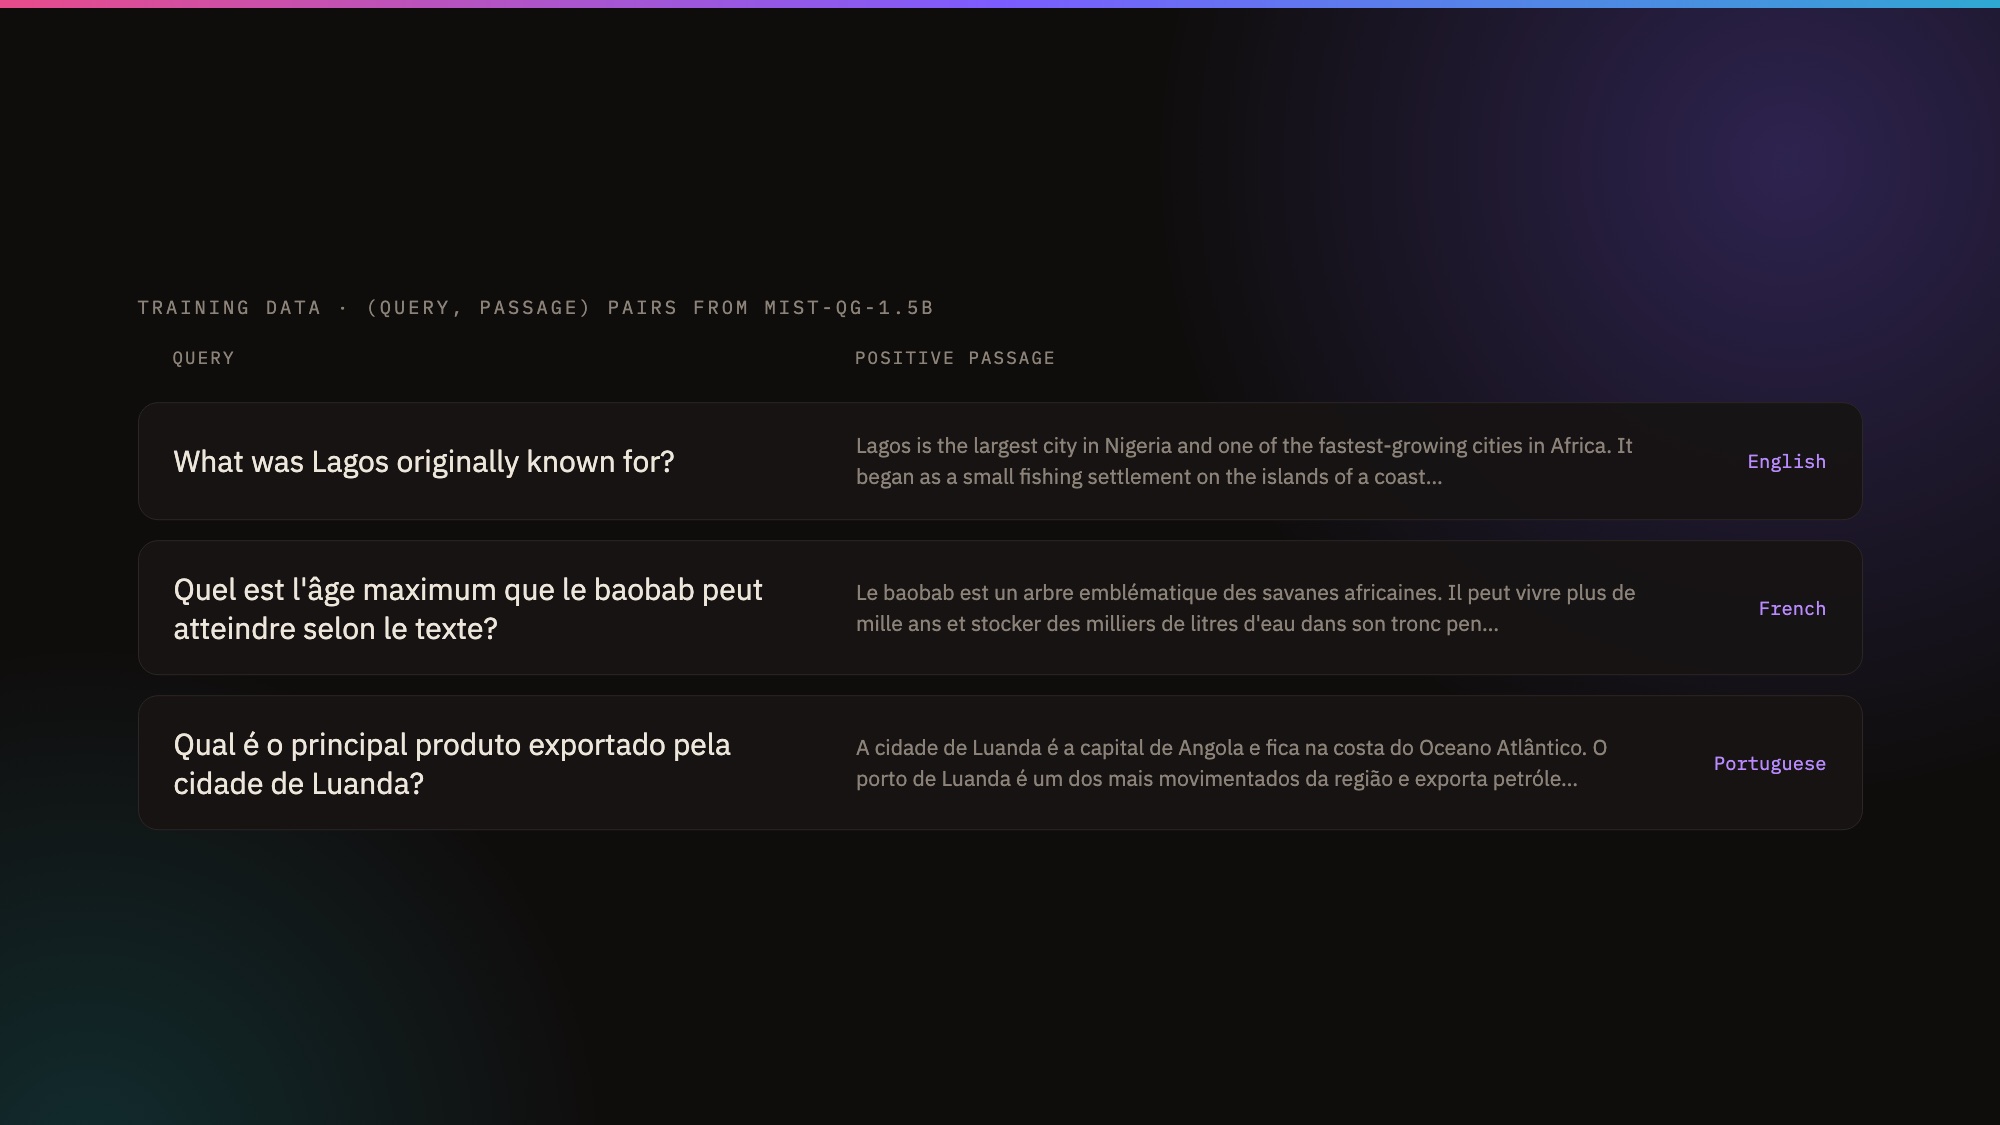
Retrieval training data
Generate verified (question, passage) pairs from your own corpus in 324 languages, or across languages, and fine-tune retrievers and rerankers on data that matches your domain.
Not seeing yours? These are the pipelines we can point at published benchmarks for. Anything adjacent — a different language, a different task, your own data — we build to order.
Want one of these in your product?
Every model here is open-weight, so you can build any of it yourself today. If you would rather we adapted it to your data and shipped it, that is what Olaverse for Business does.